 FinTech
 USA
AI Mortgage Loan Platform
AI-driven mortgage workspace where the Genie engine matches borrowers to the right loan across 50,000+ lender documents in milliseconds.
AI model tuning and optimization services that improve accuracy, cut inference latency, and lower infrastructure cost. We fine-tune pre-trained models with LoRA, QLoRA, and RLHF for businesses across 20+ industries.


The advantage of ai model tuning and optimization services is measurable lift across accuracy, latency, and cost. Here is what you gain when you ship with our team.
Lifts prediction accuracy 40% with LoRA fine-tuning on your proprietary data. This is especially valuable for ML leads protecting model SLAs.
Cuts inference latency 70% with architecture optimization and quantization. This is especially valuable for product teams with sub-second SLOs.
Cuts GPU infrastructure cost 60% through compression, quantization, and efficient batching. This is especially valuable for FinOps leads cutting cloud spend.
Doubles model useful life with continuous retraining as data patterns evolve. This is especially valuable for data science leaders managing model fleets.
Our AI and LLM optimization services compress models 90% for mobile, IoT, and edge. This is especially valuable for hardware-constrained product teams.
We deliver fine-tuning, RLHF, quantization, and distillation across model families like LLaMA, Mistral, GPT, and Falcon, lifting accuracy, latency, and cost-efficiency.
We adapt pre-trained models to your domain using LoRA and QLoRA parameter-efficient fine-tuning, lifting accuracy on your data without the full-fine-tune compute bill.

We retrain models on your proprietary data to improve predictions that are directly relevant to your industry and workflows.
We accelerate development by fine-tuning existing pre-trained models instead of training from scratch, saving time and compute.
We systematically tune learning rates, batch sizes, and architectures to find the configuration that maximizes model accuracy.
We adapt models to new tasks with minimal labeled data, ideal when you have limited training examples available.
See how we have helped businesses improve AI accuracy and reduce inference costs through fine-tuning across LLaMA, Mistral, GPT, and Falcon models.
FinTechUSAAI-driven mortgage workspace where the Genie engine matches borrowers to the right loan across 50,000+ lender documents in milliseconds.
A high-performance AV distribution platform enabling centralized device control, seamless IP-based streaming, automated workflows, and real-time diagnostics for complex installations.
 Travel and TourismIraq
A centralized travel management platform that streamlines trip planning, tourist coordination, financial operations, role-based access, reporting, and real-time communication.
 On-DemandUSA
AI-powered visual recognition platform that identifies images, extracts text, and helps users quickly search for and locate exact visual content.
 PhotographyUSA
AI-powered platform that turns real estate photos into staged, enhanced, dusk-lit visuals and property videos, cutting delivery time from days to minutes and costs by nearly 10x.
 Mobility & LogisticsArgentina
Real-time parking app connecting drivers with available street parking through location-based matching, live tracking, secure communication, and seamless in-app transactions.
We pair industry-leading ML frameworks with hardened MLOps tooling so every fine-tuning run is reproducible, observable, and shippable to any deployment target.
 Python
 TensorFlow
 PyTorch
 Keras
Our six-step approach delivers AI model training and optimization services that produce measurable, production-grade performance lift on every engagement.
We analyze your model architecture, performance metrics, and business goals. We identify the specific areas where fine-tuning and optimization will deliver the biggest impact.
We prepare high-quality training data for fine-tuning, including data cleaning, augmentation, and domain-specific labeling for your use case.
We establish performance baselines and benchmark your current model against industry standards to measure improvement accurately.
We systematically optimize model parameters using grid search, random search, and Bayesian optimization techniques for maximum accuracy.
We retrain models iteratively, validating against held-out test data to ensure improvements generalize to real-world scenarios.
Post-deployment, we monitor model accuracy, latency, and drift. We retrain when performance degrades to maintain optimal results.
With 15+ years of experience, we have delivered 700+ projects across 20+ industries. Our ai model tuning and optimization services drive real, measurable improvements.
Projects delivered successfully using 50+ technologies
Projects delivered successfully using 50+ technologies
In-house experts with average 4+ years of experience
In-house experts with average 4+ years of experience
App store downloads with 96%+ crash-free users
App store downloads with 96%+ crash-free users
Senior-level AI specialists on staff
Senior-level AI specialists on staff
Happy clients and 60% recurring business
Happy clients and 60% recurring business
Industries served across 25+ countries
Industries served across 25+ countries
Hear from businesses that lifted accuracy, cut latency, and shipped tuned models to production with our ML engineering team.
Christopher Howat
Co-Founder
Marcus & Company Realty LLC - Florida
WebMob's team jumped in without hesitation, working after hours to keep our project running smoothly. Their project managers, developers, and QA are all top tier.
Jon Kommas
Marketing & Brand Strategist
ME Gaming - USA
WebMobTech understood our perspective, met every requirement, executed quickly, stayed transparent with a clear project process, and handled time zone differences well.
Daniel Stirkman
CEO
Eifo - Argentina
WebMob Technologies was committed to our project's success, meeting every requirement quickly and professionally. Both apps launched successfully with positive user feedback.
Ricard Mallart
Operation Manager
Skale
WebMob Technologies delivered all requirements on time, stayed in constant touch via Slack and Asana, found effective solutions, and ensured a successful collaboration.
Daafram Campbell
CEO & Co-Founder Social Networking Startup - USA
WebMob Technologies stands out for its highly skilled team. They delivered outstanding results, reflected in strong user downloads, retention, and positive user feedback.
Luke Monroe
CEO
Kendrick Realty & Houzquest - USA
WebMob Technologies delivered fast, user-friendly, responsive solutions. The team communicated effectively across time zones and provided valuable insights to improve the final product.
Michelle Lester
Operation Manager
Primally Nourished - USA
WebMob met every requirement, used modern technologies, and delivered great value. Their work helped us gain 5K+ paid subscribers in a short time.
Eyal Gerber
CEO
SoftaCheck - Israel
WebMobTech stood out for its attentiveness and professionalism. The collaboration was smooth from start to finish, and the team consistently delivered exactly what we needed.
Fine-tuning separates a model that runs from one that wins. Our engineers turn weak models into production assets.
Our model fine-tuning work improves AI performance across seven sectors with measurable lift on accuracy, latency, and cost. Here is where model optimization creates the biggest impact.
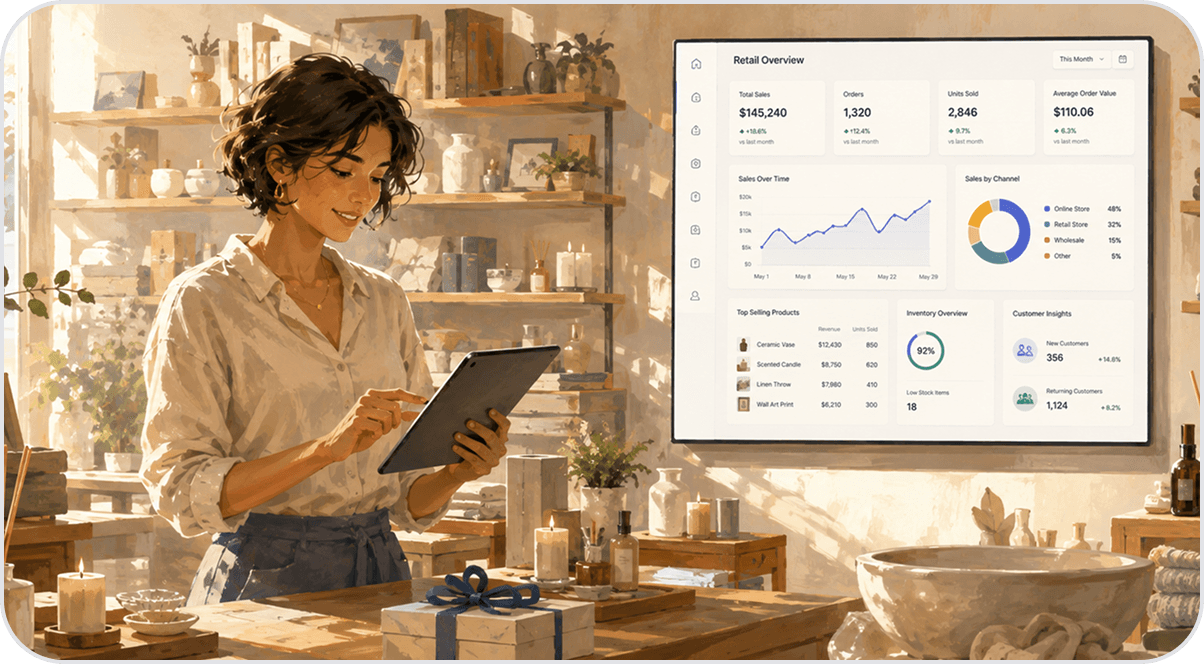
Recommendation accuracy and inference costs optimized for e-commerce.
WebMob Technologies has delivered work that exceeded client expectations across global markets. Clutch has recognized us as Top Developers and Global Leading B2B Firm for six consecutive years.
Start with a no-cost Model Performance Audit, then get fine-tuning that boosts accuracy and speeds up inference.
Going live is just the start. We work in your timezone post-launch, monitoring drift and retuning models so peak performance holds as data evolves.
We track model accuracy, latency, and drift daily, spotting issues before they impact your business decisions.
We retrain and recalibrate models with fresh inputs as data evolves, keeping predictions sharp and AI relevant.
We continuously optimize your compute resources and inference pipelines to reduce costs while maintaining or improving model performance.
Direct access to the ML engineers who optimised your models. No queues. Real experts, always.
44 reviews on Clutch
Share your rough idea on a short call, and get a scoped plan back within two business days.


Get Your Project Quote In Just 24 Hours!
Got questions about ai model tuning and optimization services? Here are the most common ones we hear from US and global ML teams.
Fine-tuning adjusts a pre-trained AI model so it performs better on your specific data and business use case. We use full fine-tuning for small models and parameter-efficient methods like LoRA, QLoRA, and adapters for larger LLMs, which delivers domain-relevant accuracy without retraining the whole model.
Model optimization improves efficiency, accuracy, and speed of AI systems while reducing infrastructure costs. The benefit of AI model tuning is that one round of compression, quantization, and architecture tweaks often pays back the engagement in cloud savings within a quarter, then keeps compounding.
Timeline depends on model complexity and data readiness. A LoRA fine-tuning rollout on an open-source LLM takes 2 to 4 weeks. Enterprise-grade engagements with custom data pipelines, RLHF, and full evaluation harness work typically take 3 to 6 months. We share a phased delivery plan upfront after a free discovery call.
Cost varies by model size, optimization targets, and data readiness. A LoRA fine-tuning pilot on an open-source model can start in the low five figures, while enterprise RLHF and full optimization stacks scale up. We provide a tailored quote after a model performance audit so the scope matches your ROI ambition.
Transforming businesses with AI, Cloud, and Mobile excellence since 2010.


© 2026 WebMobTech Solutions Pvt.Ltd. All Rights Reserved.
D-U-N-S Number: 860386955
CIN: U74999GJ2016PTC092785