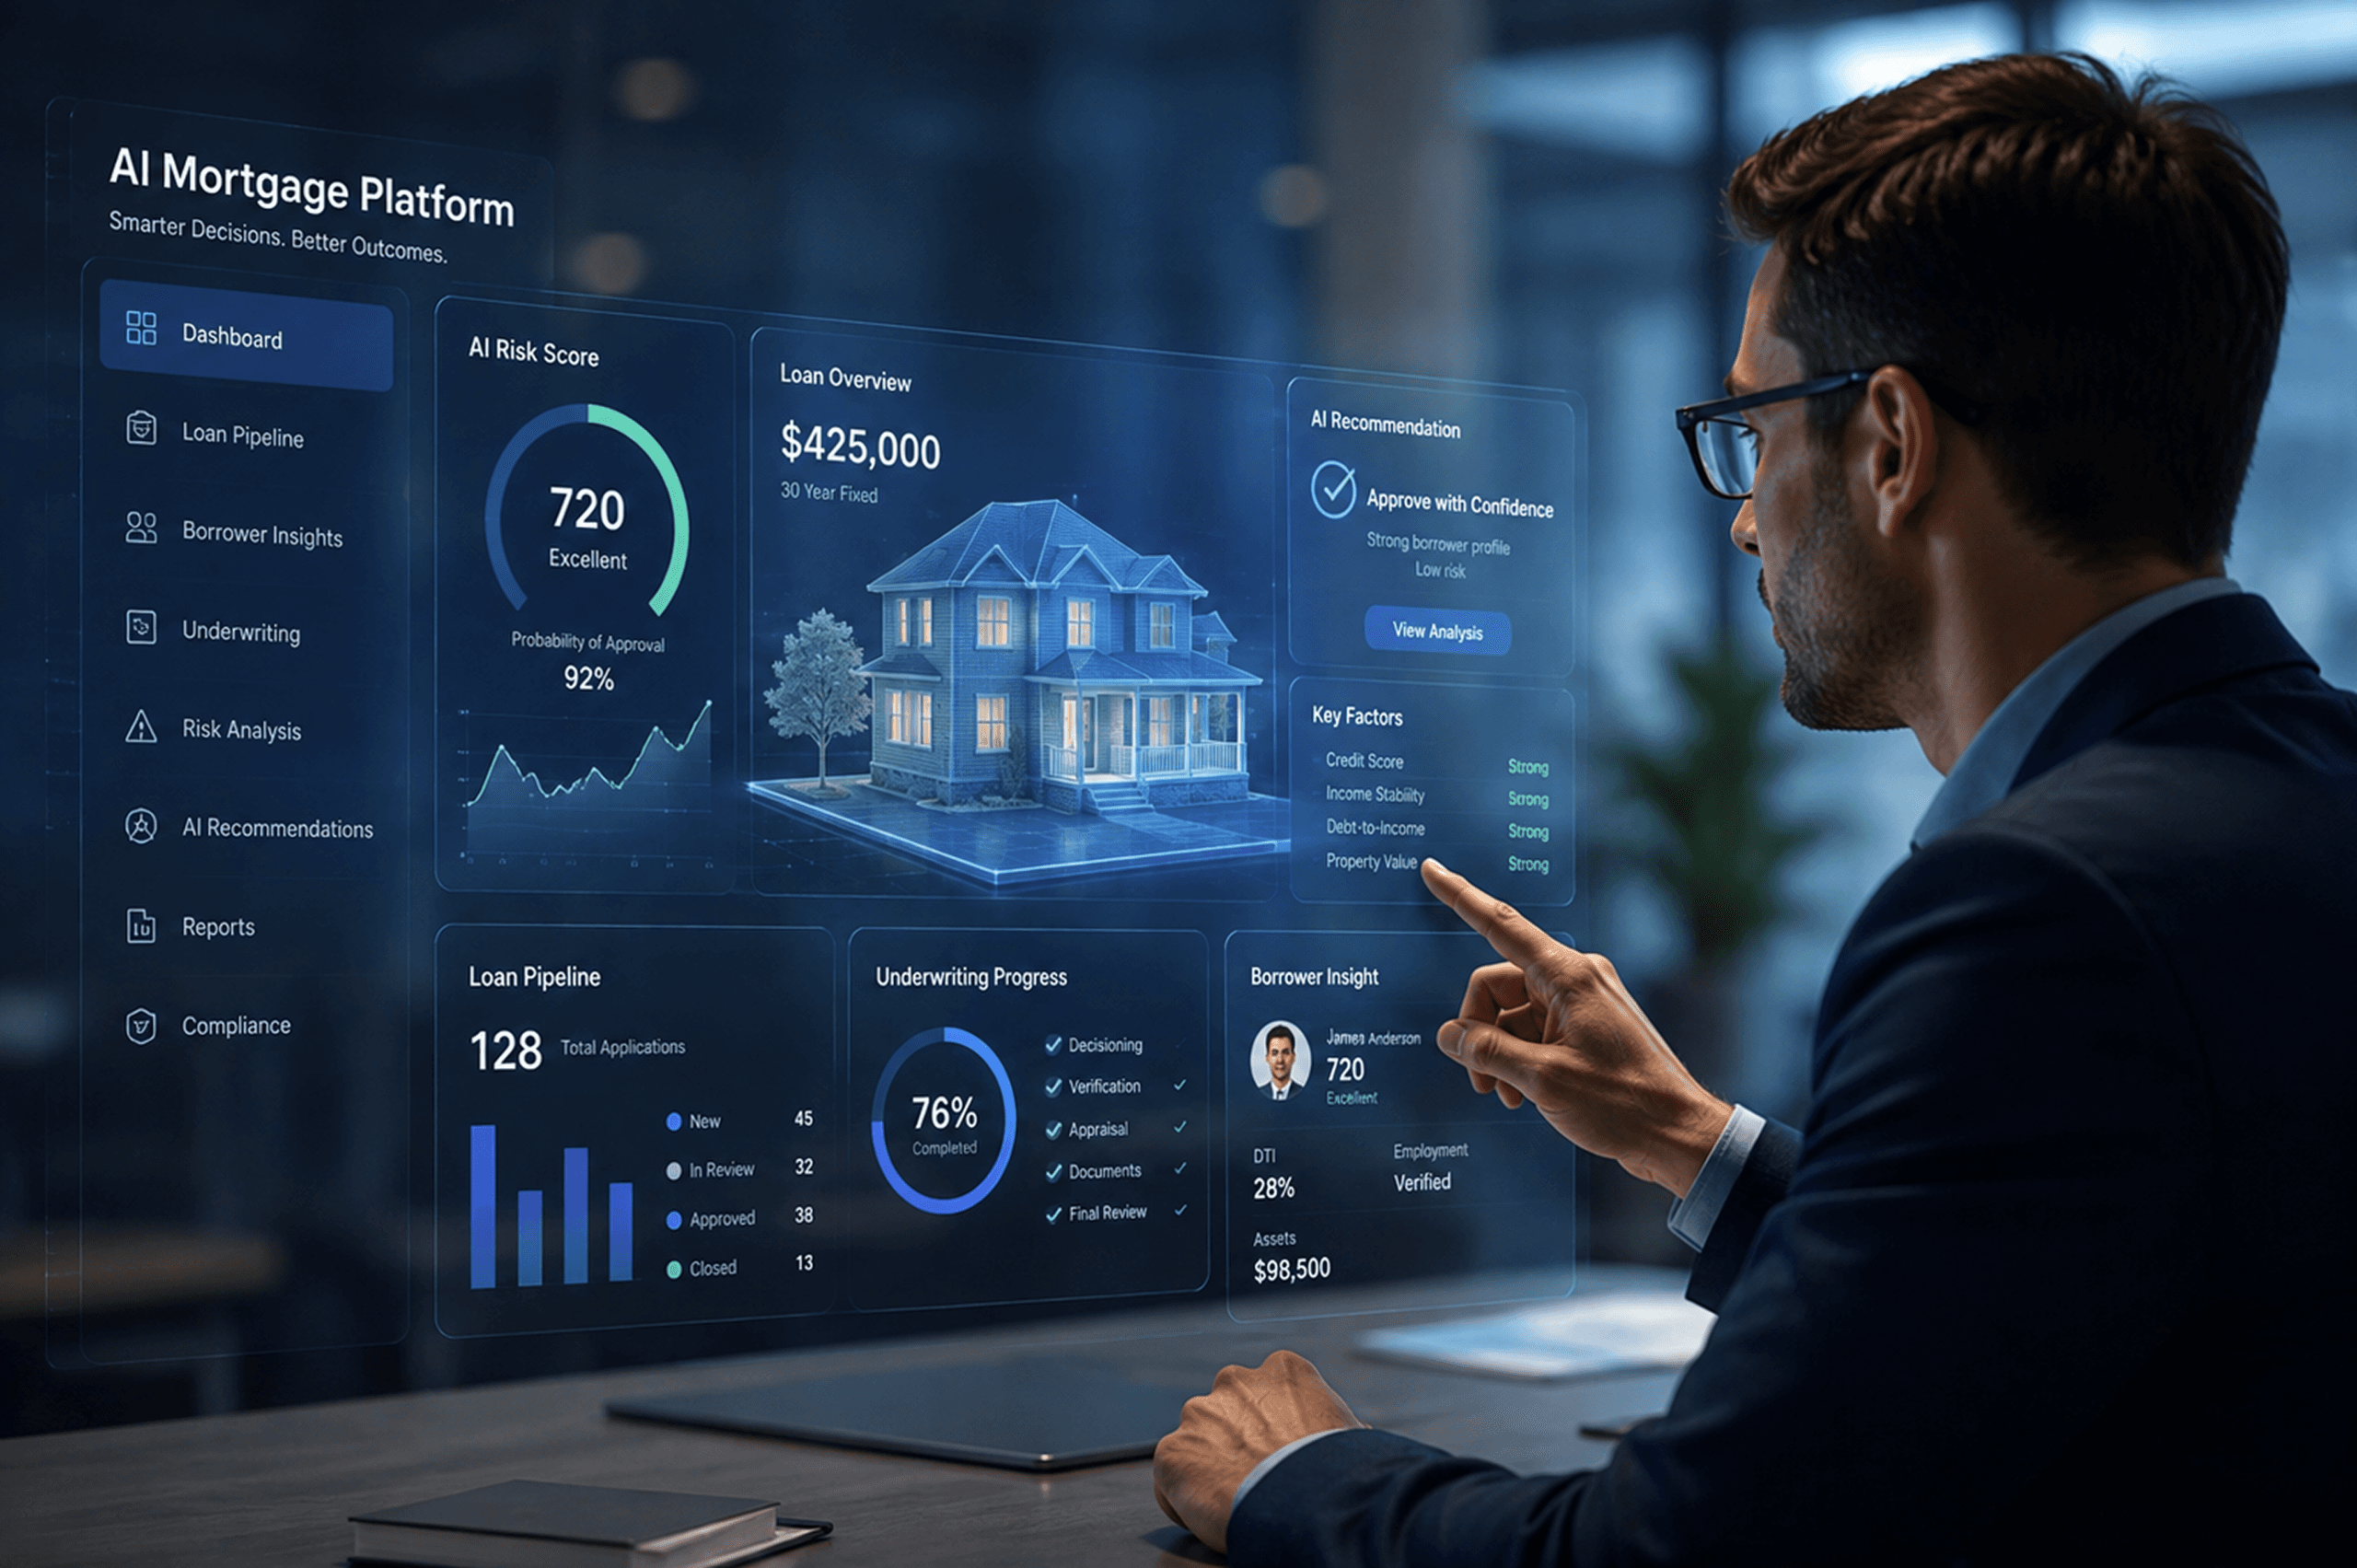
 FinTech
 USA
AI Mortgage Loan Platform
AI-driven mortgage workspace where the Genie engine matches borrowers to the right loan across 50,000+ lender documents in milliseconds.
Build smarter systems with our LLM Development Services. From custom LLM development to seamless integration, we deliver AI-driven systems designed to enhance decision-making and customer engagement.


The advantage of our large language model development services is custom language AI that outperforms generic tools across 150+ LLM-specific deployments. Here is what you gain.
Cuts content production cost 70% with automated language generation. This is especially valuable for marketing teams scaling multi-channel campaigns.
Lifts response accuracy 40% with domain fine-tuning. This is especially valuable for support leads cutting deflection-error rates.
Cuts API cost 60% with self-hosted open-source models. This is especially valuable for FinOps leads cutting AI cloud spend.
Saves teams 500+ hours each month on document processing and report generation through custom llm development services. This is valuable for ops leads.
Cuts hallucination rate to under 5% with RAG and grounding through llm integration services. This is valuable for compliance-sensitive teams.
We build large language models on Mistral 7B, Phi-2, LLaMA 3.1, and Falcon foundation bases, trained on your domain data for industry-specific accuracy.
We train LLMs on your proprietary data including documents, conversations, and knowledge bases for expert-level understanding.
We customise Llama, Mistral, and other open-source models for private deployment on your own infrastructure securely.
We design LLM systems with load balancing, caching, and failover for reliable production performance at scale.
We build systems that route queries to the optimal model based on complexity, cost, and accuracy requirements.
We adapt foundation models with LoRA, QLoRA, instruction tuning, and RLHF to your use case, improving accuracy and reducing hallucinations to under 5%.
We train models to follow your specific instructions and output formats consistently for reliable business workflows.
We use human feedback to align model outputs with your quality standards and brand voice for better results.
We use efficient fine-tuning methods that deliver custom model quality at a fraction of the full training cost.
We measure fine-tuned model performance against baselines to prove improvements before production deployment.
We build RAG systems on Pinecone, Weaviate, Chroma, and Qdrant vector databases that ground LLM responses in your real data, eliminating hallucinations and ensuring factual outputs.
We connect your LLM to internal documents, databases, and APIs so it answers from your real data, not guesses.
We build and optimize vector stores using Pinecone, Weaviate, or ChromaDB for fast, accurate retrieval.
We design the data pipeline that breaks documents into searchable chunks optimized for your specific queries.
We build systems that show which documents the LLM used to generate each answer for transparency and trust.
We connect large language models to your existing CRM, ERP, and CMS through clean APIs and function calling, with prompt-injection defenses and observability baked in.
We design the integration layer with authentication, rate limiting, and fallback mechanisms for reliable, production-grade AI deployment.
We connect LLMs to Salesforce, HubSpot, SAP, and other platforms so AI works within your existing workflows.
We deploy LLM-powered bots on web, mobile, WhatsApp, and Slack from a unified codebase for consistent experiences.
We connect modern LLMs to older systems through APIs and middleware without requiring costly platform rewrites.
We help you choose the right LLM approach, foundation model, and architecture for your large language model development services project from day one.
We evaluate your data, infrastructure, and use cases to determine the fastest path to LLM value for your business.
We recommend GPT-4, Llama, Mistral, or Claude based on your accuracy, cost, and privacy requirements.
We help you decide whether to fine-tune, use APIs, or train from scratch based on your specific budget and needs.
We create a phased plan with timelines and milestones so you can hire llm developers and move forward with confidence.
We track BLEU, ROUGE, perplexity, hallucination rate, and inference cost daily, then continuously improve your LLM systems through ongoing llm development services and tuning.
We track response accuracy, relevance, and safety metrics daily to catch degradation before it impacts users.
We reduce API and compute costs through caching, prompt optimization, and model selection strategies.
We design and optimize prompt templates that consistently produce high-quality outputs for your specific workflows.
We test different models, prompts, and configurations to continuously improve performance and user satisfaction.
We deliver llm services across GPT-4o, Claude, Gemini, LLaMA, and Mistral, from custom training to RAG implementation, fine-tuning, and enterprise integration.

We build large language models on Mistral 7B, Phi-2, LLaMA 3.1, and Falcon foundation bases, trained on your domain data for industry-specific accuracy.
We train LLMs on your proprietary data including documents, conversations, and knowledge bases for expert-level understanding.
We customise Llama, Mistral, and other open-source models for private deployment on your own infrastructure securely.
We design LLM systems with load balancing, caching, and failover for reliable production performance at scale.
We build systems that route queries to the optimal model based on complexity, cost, and accuracy requirements.

We adapt foundation models with LoRA, QLoRA, instruction tuning, and RLHF to your use case, improving accuracy and reducing hallucinations to under 5%.
We train models to follow your specific instructions and output formats consistently for reliable business workflows.
We use human feedback to align model outputs with your quality standards and brand voice for better results.
We use efficient fine-tuning methods that deliver custom model quality at a fraction of the full training cost.
We measure fine-tuned model performance against baselines to prove improvements before production deployment.
We build RAG systems on Pinecone, Weaviate, Chroma, and Qdrant vector databases that ground LLM responses in your real data, eliminating hallucinations and ensuring factual outputs.
We connect your LLM to internal documents, databases, and APIs so it answers from your real data, not guesses.
We build and optimize vector stores using Pinecone, Weaviate, or ChromaDB for fast, accurate retrieval.
We design the data pipeline that breaks documents into searchable chunks optimized for your specific queries.
We build systems that show which documents the LLM used to generate each answer for transparency and trust.
We connect large language models to your existing CRM, ERP, and CMS through clean APIs and function calling, with prompt-injection defenses and observability baked in.
We design the integration layer with authentication, rate limiting, and fallback mechanisms for reliable, production-grade AI deployment.
We connect LLMs to Salesforce, HubSpot, SAP, and other platforms so AI works within your existing workflows.
We deploy LLM-powered bots on web, mobile, WhatsApp, and Slack from a unified codebase for consistent experiences.
We connect modern LLMs to older systems through APIs and middleware without requiring costly platform rewrites.
We help you choose the right LLM approach, foundation model, and architecture for your large language model development services project from day one.
We evaluate your data, infrastructure, and use cases to determine the fastest path to LLM value for your business.
We recommend GPT-4, Llama, Mistral, or Claude based on your accuracy, cost, and privacy requirements.
We help you decide whether to fine-tune, use APIs, or train from scratch based on your specific budget and needs.
We create a phased plan with timelines and milestones so you can hire llm developers and move forward with confidence.
We track BLEU, ROUGE, perplexity, hallucination rate, and inference cost daily, then continuously improve your LLM systems through ongoing llm development services and tuning.
We track response accuracy, relevance, and safety metrics daily to catch degradation before it impacts users.
We reduce API and compute costs through caching, prompt optimization, and model selection strategies.
We design and optimize prompt templates that consistently produce high-quality outputs for your specific workflows.
We test different models, prompts, and configurations to continuously improve performance and user satisfaction.
See how we have helped businesses build production-grade language AI through our llm development services and engineering teams.
FinTechUSAAI-driven mortgage workspace where the Genie engine matches borrowers to the right loan across 50,000+ lender documents in milliseconds.
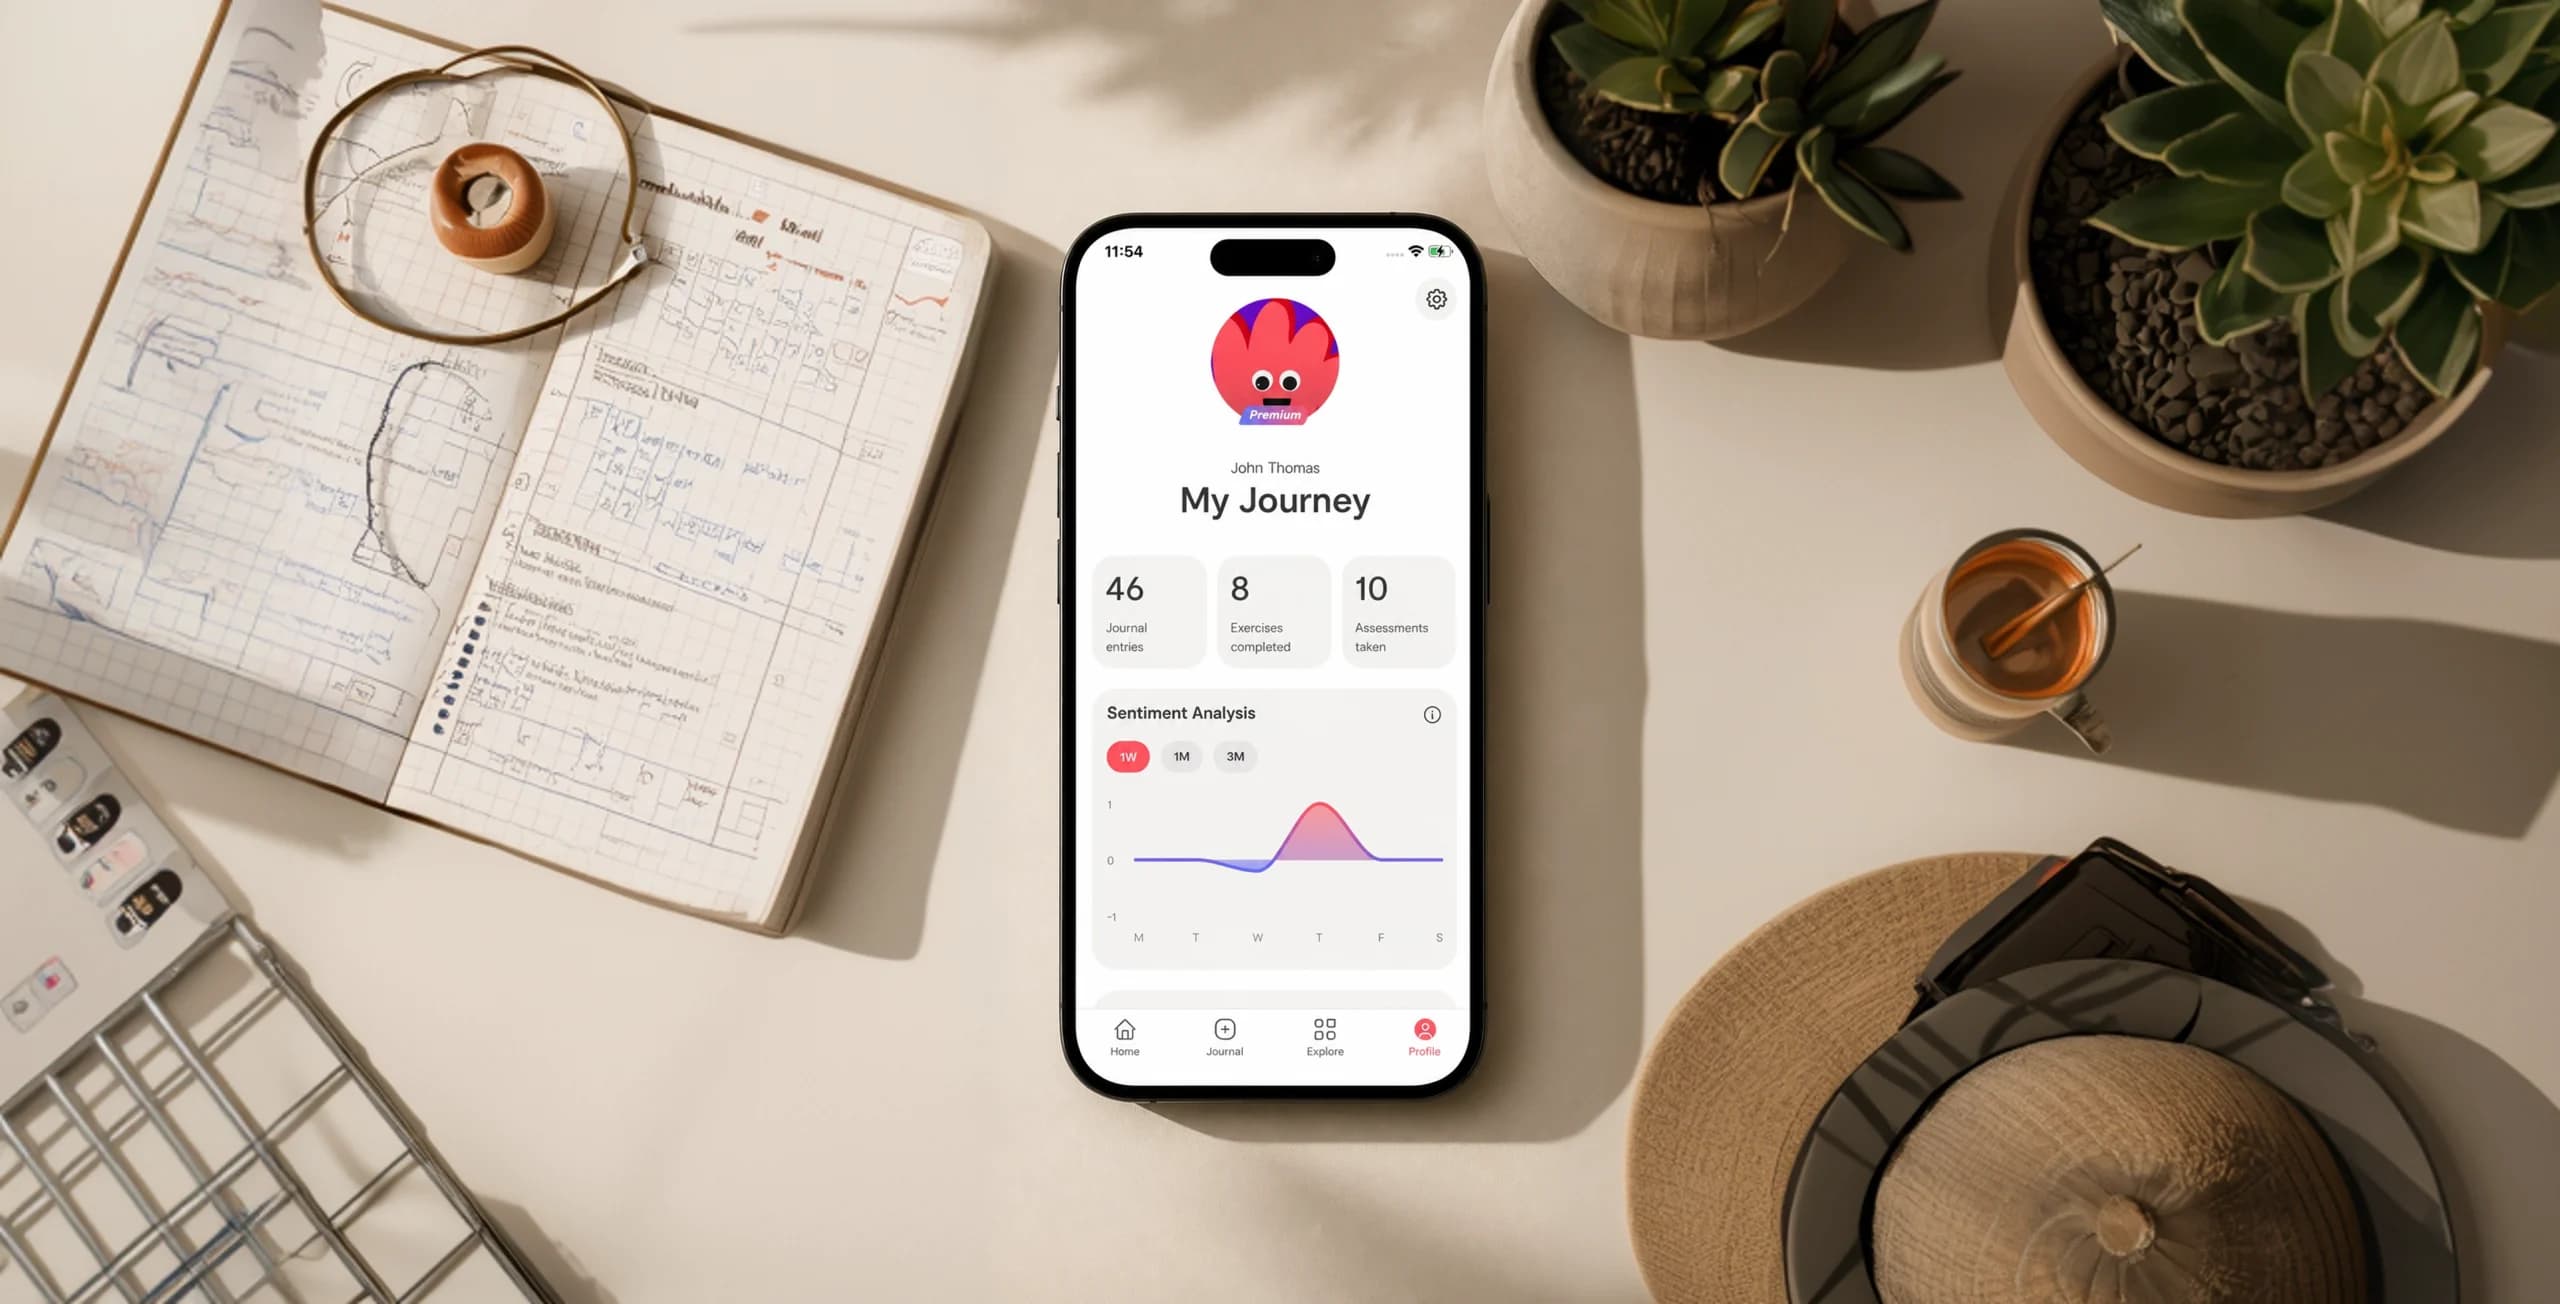 Healthcare & Life SciencesUK
AI-powered mental wellness app combining personalized exercises, journals, and intelligent coaching to help users build self-awareness, manage emotions, and develop healthier daily habits.
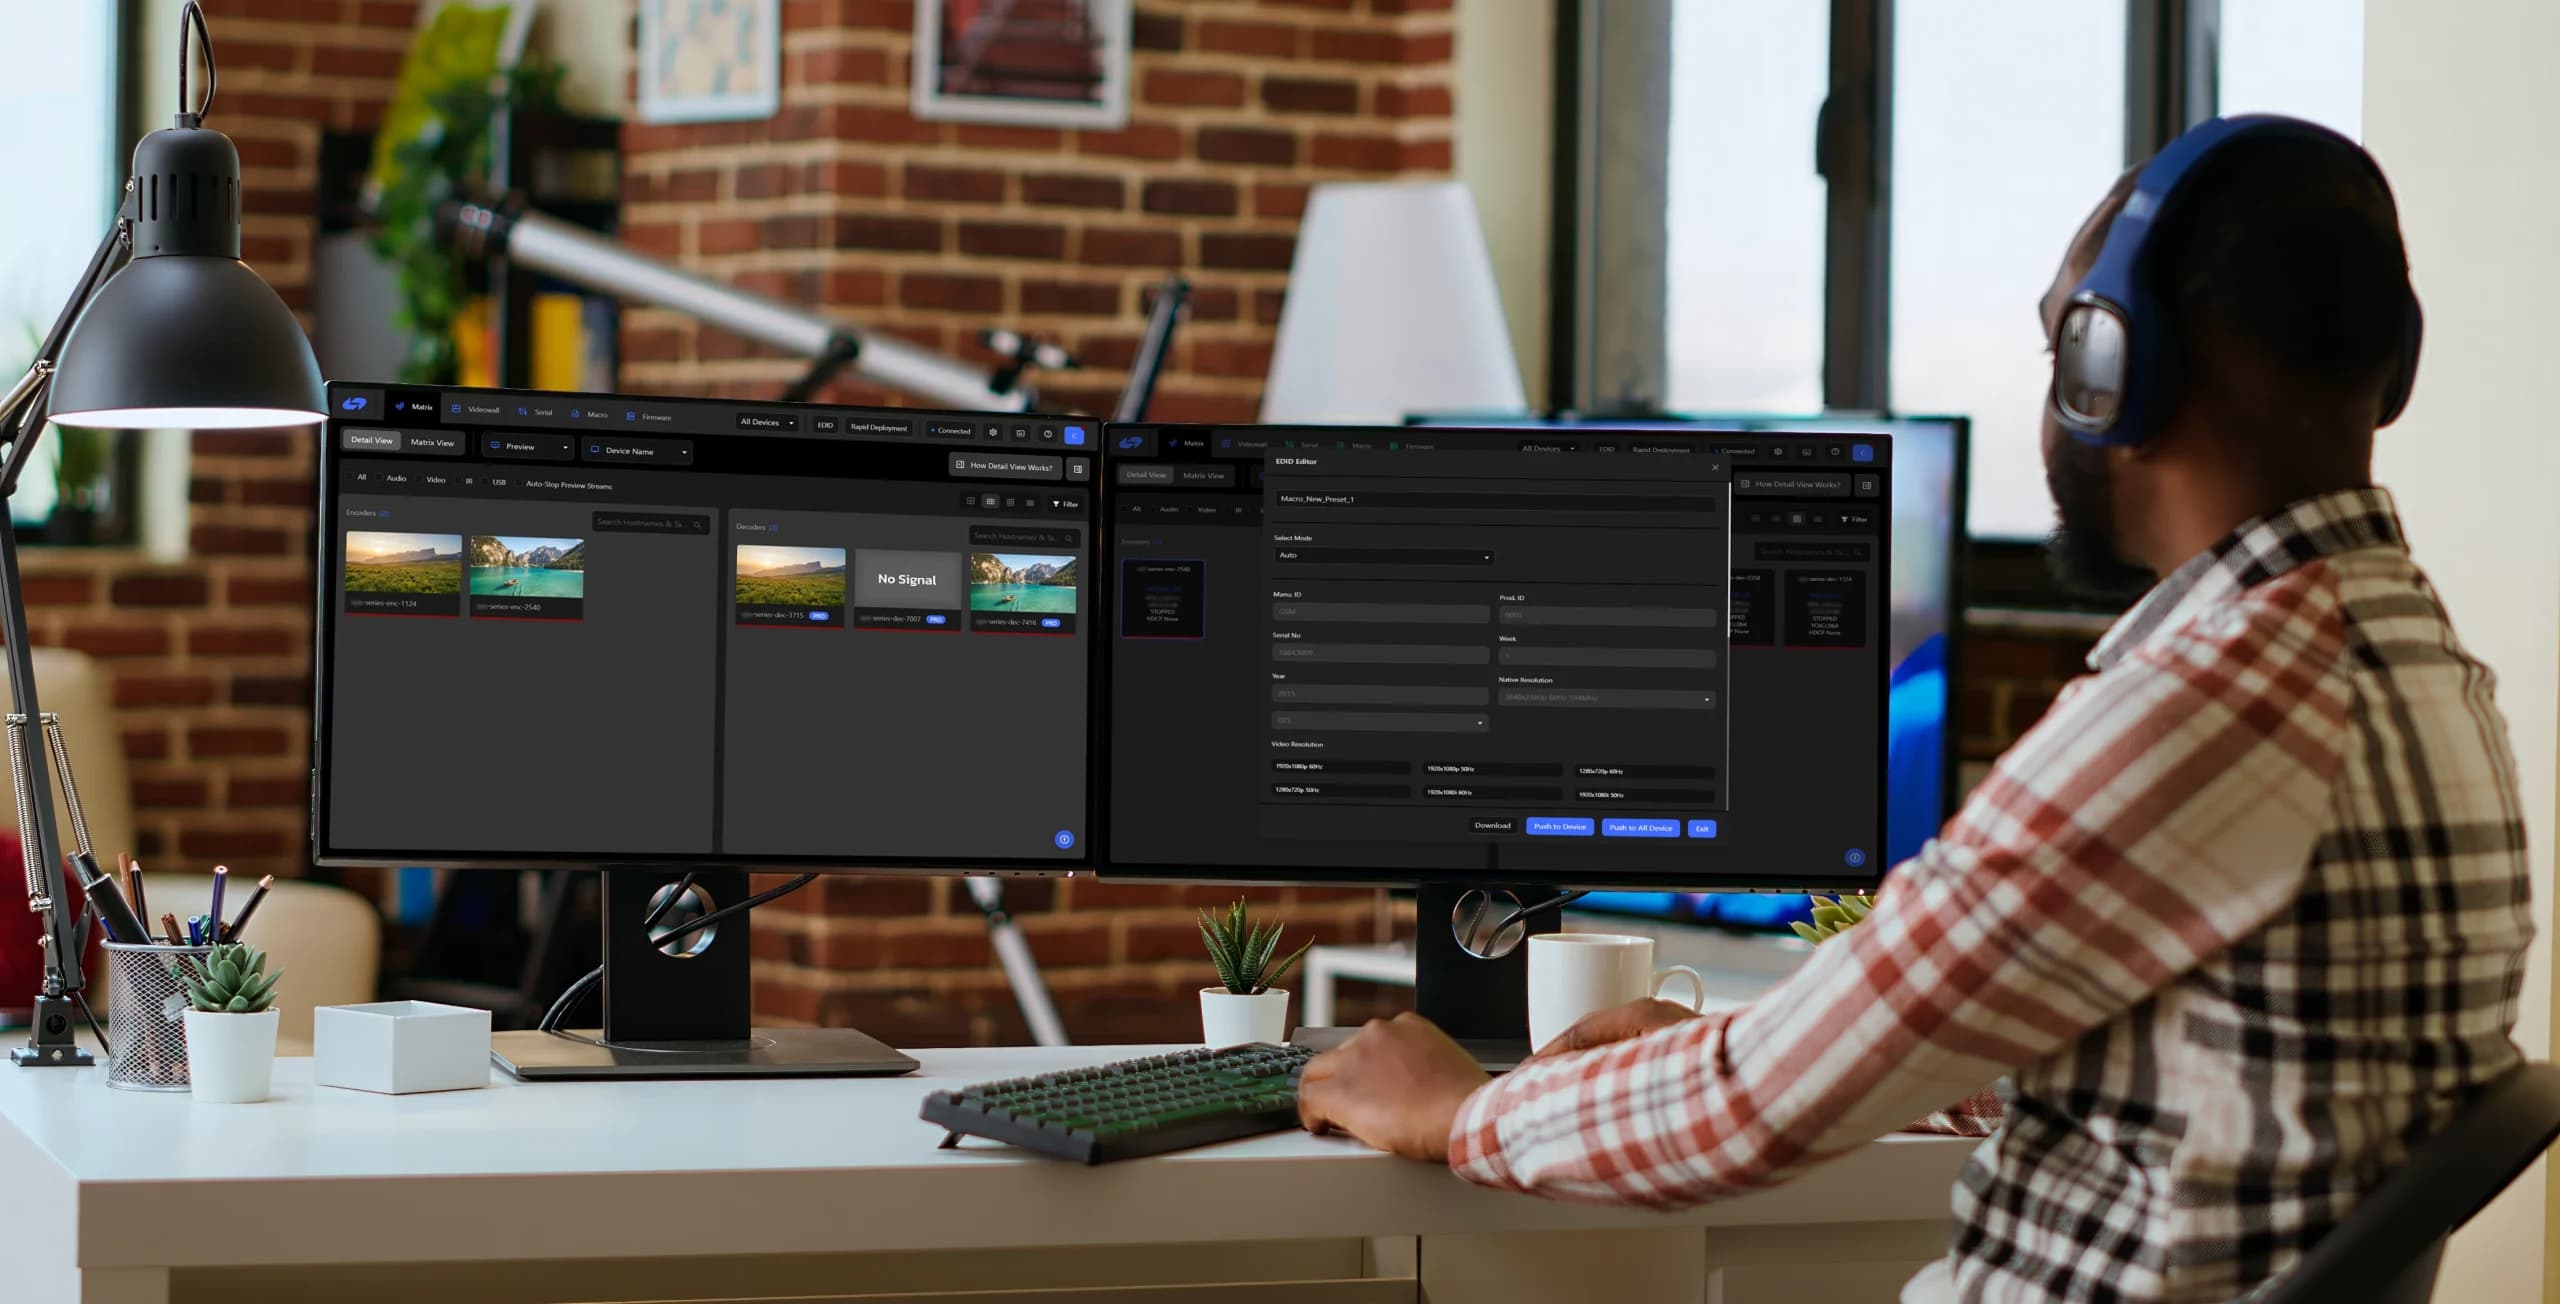
A high-performance AV distribution platform enabling centralized device control, seamless IP-based streaming, automated workflows, and real-time diagnostics for complex installations.
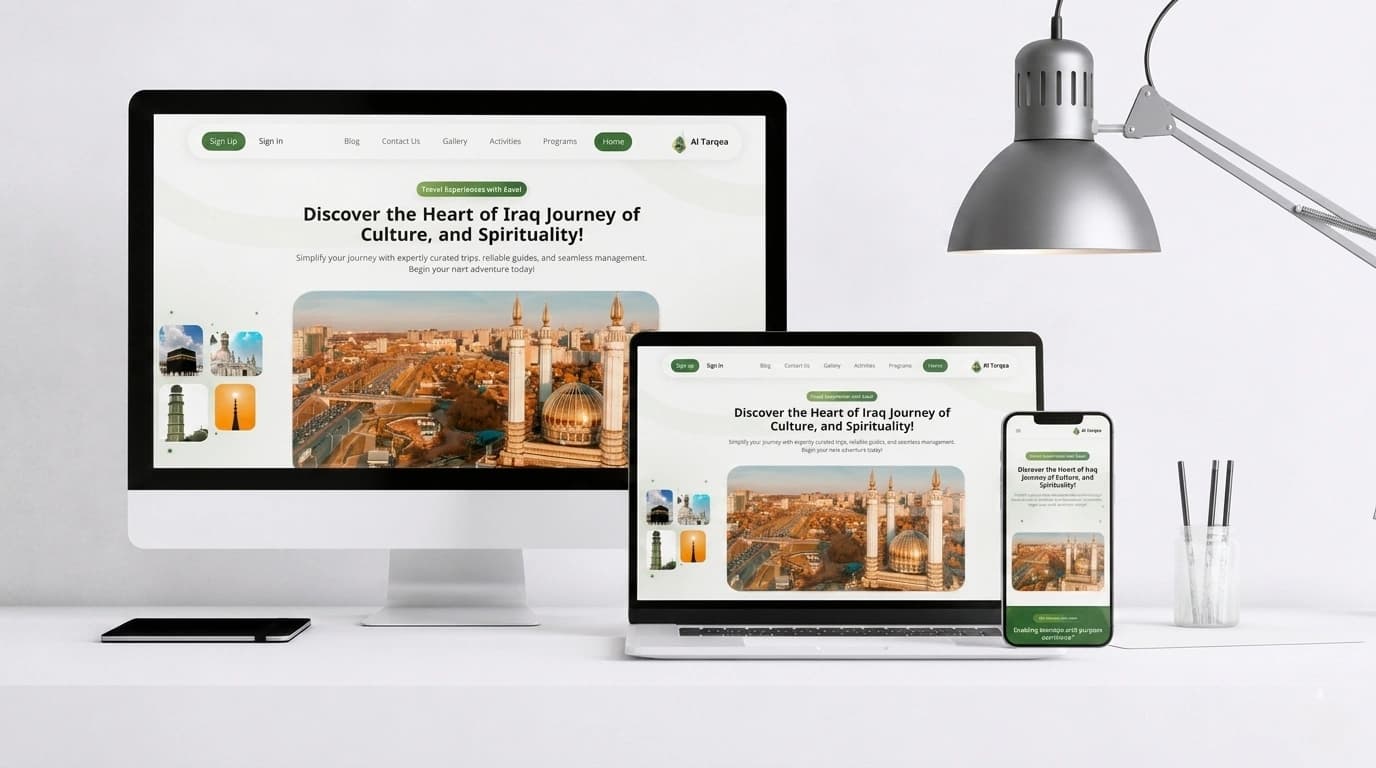 Travel and TourismIraq
A centralized travel management platform that streamlines trip planning, tourist coordination, financial operations, role-based access, reporting, and real-time communication.
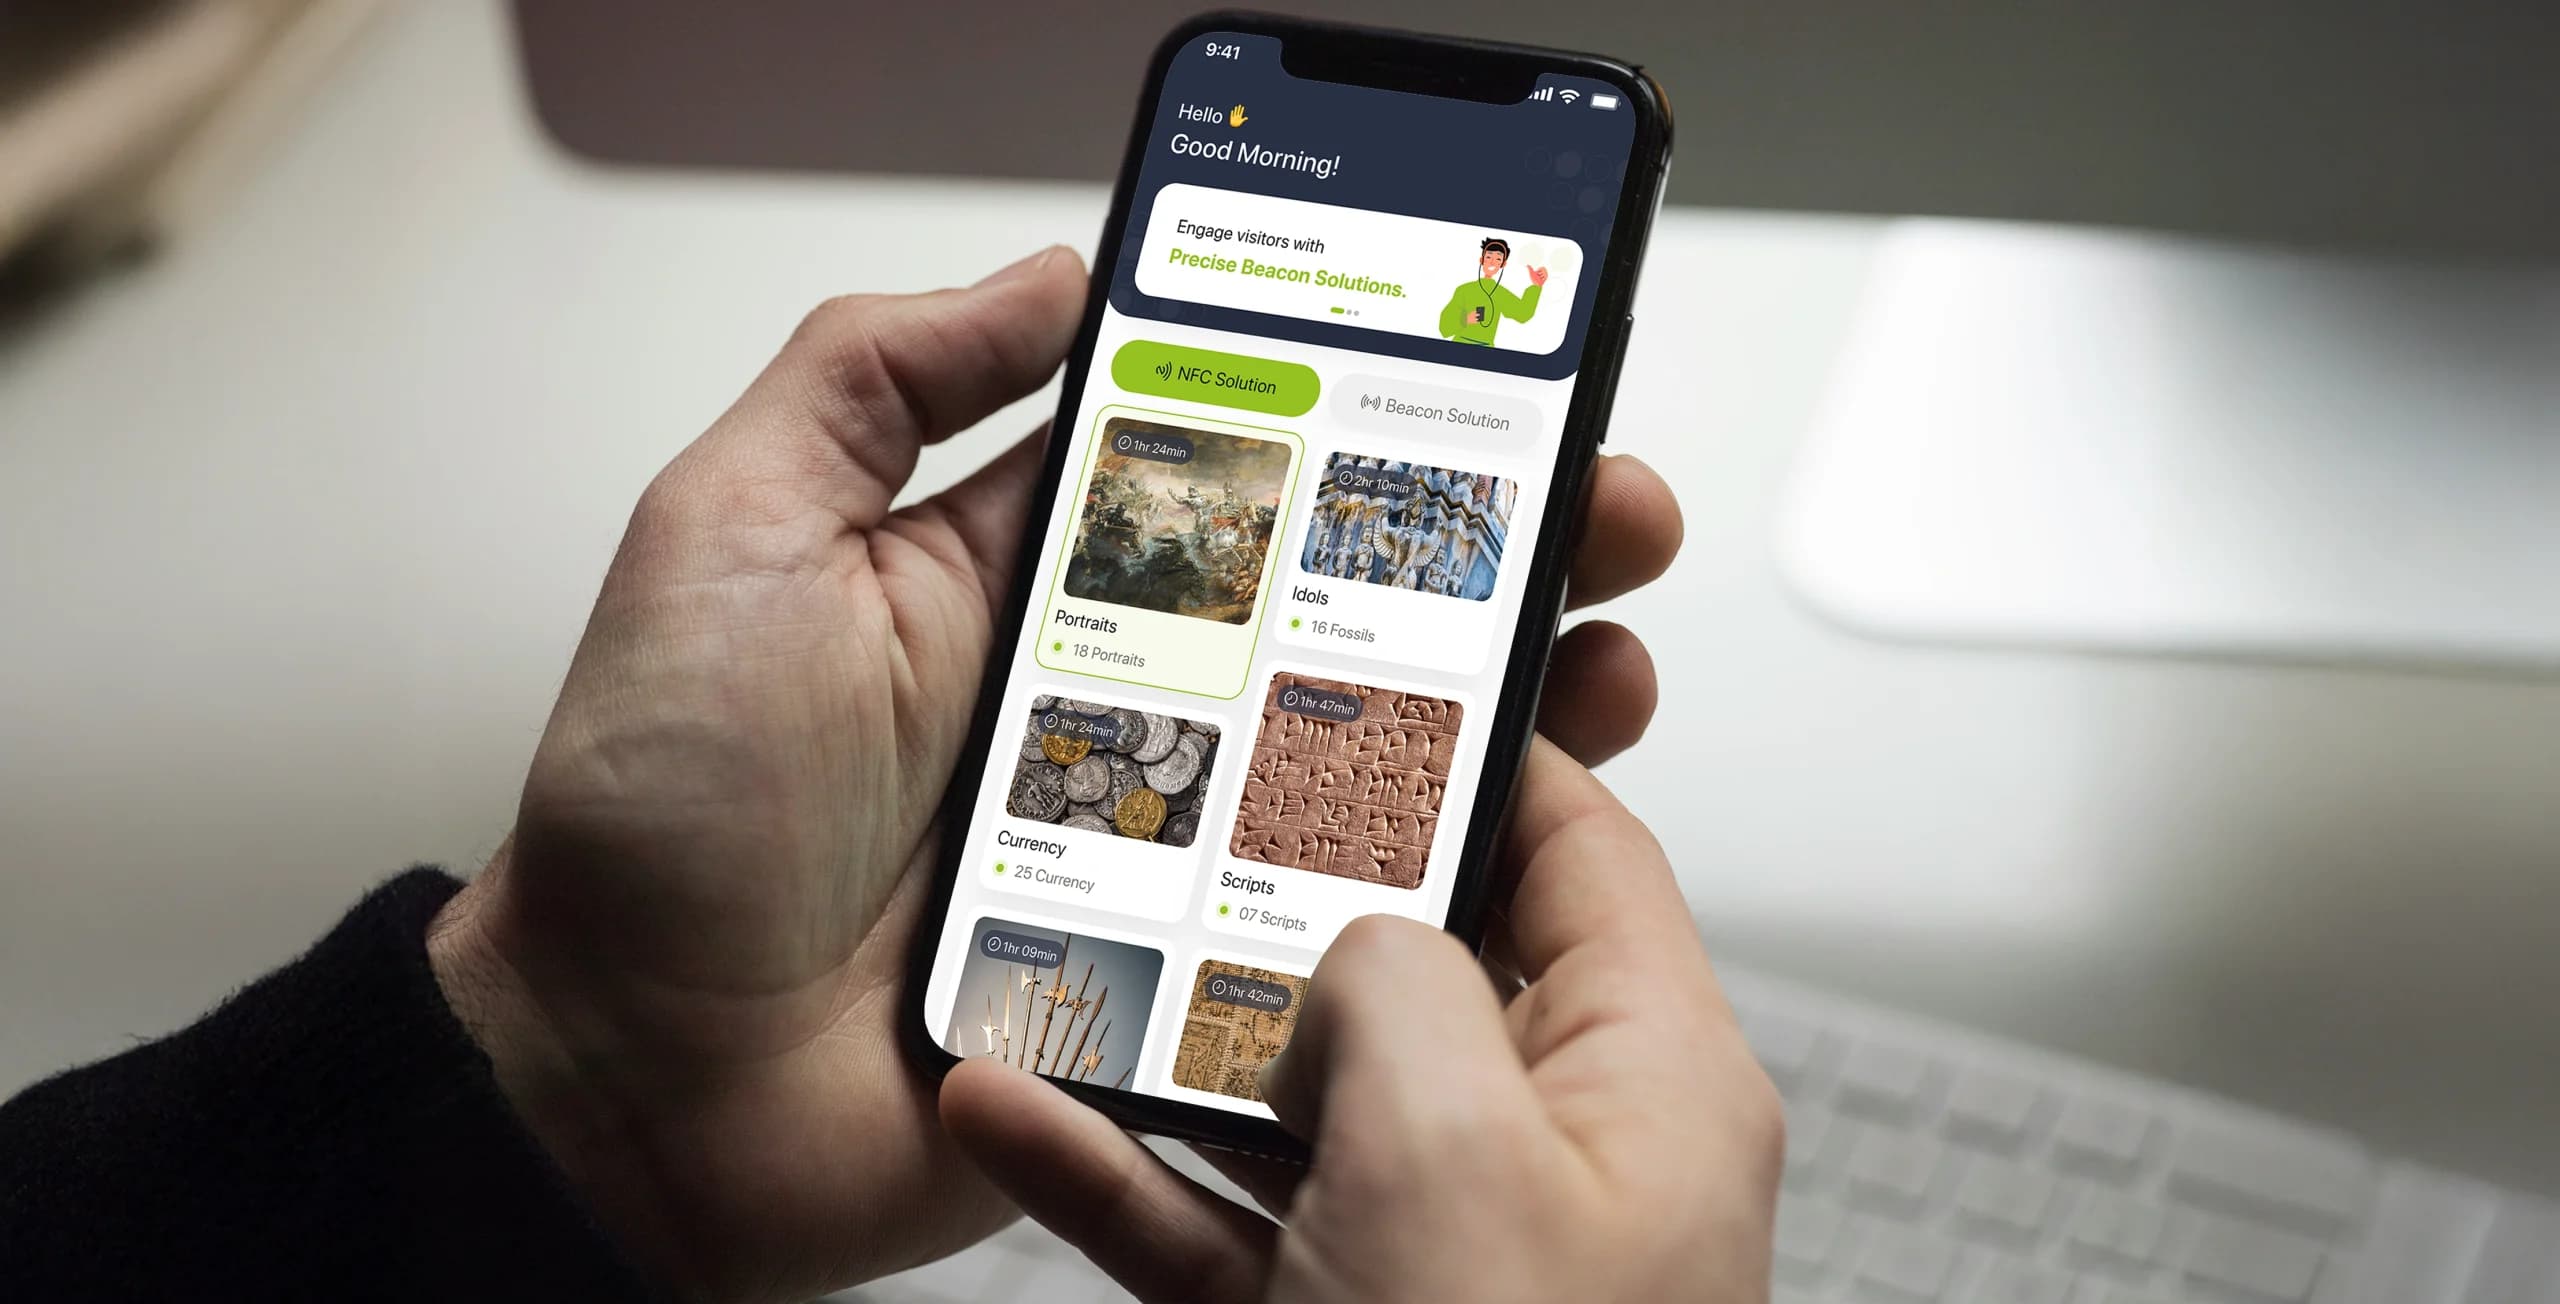 IoTItaly
Uses BLE and NFC technology to make physical spaces more accessible, enabling object recognition, location-based guidance, and voice-assisted navigation across museums, trails, and public venues.
We pair foundation models with hardened orchestration, vector stores, and inference runtimes so every llms development services engagement ships fast, reliable, and production-ready.
 GPT
 Claude
 Gemini
 Llama
 Mistral
Our six-step process delivers reliable, production-grade custom ml model development across requirement analysis, data preparation, training, validation, deployment, and continuous monitoring.
We analyze your data, business goals, and use cases. We define the model architecture, success metrics, and deployment strategy for your custom ml model development project.
We gather, clean, and label training data. Quality data is the foundation of every successful custom ml model development project we deliver.
We select the optimal algorithms and design the model architecture tailored to your specific problem using ai/ml development services expertise.
We train models on your data and systematically optimize parameters to maximize accuracy, speed, and generalization performance.
We validate models against held-out test data and real-world edge cases, benchmarking precision, recall, F1, and AUC-ROC for production-ready accuracy through ai ml software development services.
We deploy models into your systems and monitor performance continuously, retraining when accuracy degrades to maintain peak results.
With 15+ years of experience, we have delivered 700+ projects across 20+ industries. Our 120+ in-house experts build large language models that work in production.
Projects delivered successfully using 50+ technologies
Projects delivered successfully using 50+ technologies
In-house experts with average 4+ years of experience
In-house experts with average 4+ years of experience
App store downloads with 96%+ crash-free users
App store downloads with 96%+ crash-free users
Senior-level AI specialists on staff
Senior-level AI specialists on staff
Happy clients and 60% recurring business
Happy clients and 60% recurring business
Industries served across 25+ countries
Industries served across 25+ countries
Here is what clients say about working with our LLM engineers on their language AI projects.
Jon Kommas
Marketing & Brand Strategist
ME Gaming - USA
WebMobTech understood our perspective, met every requirement, executed quickly, stayed transparent with a clear project process, and handled time zone differences well.
Daniel Stirkman
CEO
Eifo - Argentina
WebMob Technologies was committed to our project's success, meeting every requirement quickly and professionally. Both apps launched successfully with positive user feedback.
Ricard Mallart
Operation Manager
Skale
WebMob Technologies delivered all requirements on time, stayed in constant touch via Slack and Asana, found effective solutions, and ensured a successful collaboration.
Daafram Campbell
CEO & Co-Founder Social Networking Startup - USA
WebMob Technologies stands out for its highly skilled team. They delivered outstanding results, reflected in strong user downloads, retention, and positive user feedback.
Luke Monroe
CEO
Kendrick Realty & Houzquest - USA
WebMob Technologies delivered fast, user-friendly, responsive solutions. The team communicated effectively across time zones and provided valuable insights to improve the final product.
Michelle Lester
Operation Manager
Primally Nourished - USA
WebMob met every requirement, used modern technologies, and delivered great value. Their work helped us gain 5K+ paid subscribers in a short time.
Eyal Gerber
CEO
SoftaCheck - Israel
WebMobTech stood out for its attentiveness and professionalism. The collaboration was smooth from start to finish, and the team consistently delivered exactly what we needed.
Andoni
CEO & Founder
Melly
WebMob Technologies delivered a high-quality app with most required features, accurately matched the UI design, met deadlines, and maintained clear, honest communication.
Partner with us to unlock the full potential of LLMs for your business. Whether you're looking to develop a custom solution or optimize an existing system, we’re here to help.
Our LLM engineers are deployed across seven sectors with measurable enterprise outcomes. Here is where LLM technology makes the biggest impact on business operations.
Delivering advanced AI solutions to streamline patient triage, accelerate drug discovery, and automate complex medical coding.
Secure models designed for real-time fraud detection, market risk analysis, and twenty-four-seven intelligent banking assistance.
Enhancing customer experience through personalized shopping assistants, predictive inventory management, and sentiment analysis of reviews.
Apply LLMs to interpret operational data, automate reporting, and optimize supply chain communication.
Automating lease document analysis, property valuation assessments, and client communication to accelerate deals and improve management efficiency.
Going live is just the start. We work in your timezone post-launch, monitoring outputs and tuning prompts so accuracy and cost hold over time.
We track LLM accuracy, hallucination rates, and response quality daily. Issues get caught before they impact users or business.
We retrain and update your LLM as your knowledge base grows, keeping responses current, accurate, and aligned.
We continuously optimise inference costs, response latency, and throughput to keep your LLM running efficiently and affordably.
You get direct access to the LLM engineers who built your solution. No ticket queues. Real experts ready to help.
Get a free LLM audit and launch scalable, business-focused AI solutions with WMT.
Got questions about LLM development? Here are the most common ones from US and global teams scoping their first large language model build.
Cost depends on scope. A pilot LLM rollout on an existing foundation model can start in the low five figures. A full custom LLM with fine-tuning, RAG, governance, and integration scales up. Pricing models include hourly rates from our LLM specialists, fixed-price projects, or dedicated team engagements based on your delivery preferences.
A proof of concept on an existing foundation model takes 2 to 3 weeks. A pilot with custom prompts, RAG, and one integration takes 6 to 8 weeks. Fine-tuning a model on your domain data typically takes 2 to 6 months. A full enterprise LLM rollout with governance and multi-system integration scales to 6 to 18 months.
OpenAI GPT-4o, Anthropic Claude 3.5, and Google Gemini lead on raw capability and ease of integration. Open-source models like LLaMA 3.1, Mistral 7B, Phi-2, and Falcon are cheaper to run at scale and avoid API lock-in. We recommend the foundation model that fits your accuracy, latency, cost, and data-privacy targets.
Yes. We deploy open-source models like LLaMA 3.1, Mistral 7B, and Phi-2 on your local servers or private cloud using inference runtimes such as vLLM, TGI, and Ollama. This is ideal for businesses where data privacy or compliance prohibits sending information to external APIs.
44 reviews on Clutch


Whether you're planning a new product or upgrading an existing one, we're here to help. Fill out the form, and we'll be in touch shortly.
Trusted by 250+ Brands Worldwide


Get Your Project Quote In Just 24 Hours!
Transforming businesses with AI, Cloud, and Mobile excellence since 2010.


© 2026 WebMobTech Solutions Pvt.Ltd. All Rights Reserved.
D-U-N-S Number: 860386955
CIN: U74999GJ2016PTC092785